SGI-STL30 里没有 unordered_map 和 unordered_set,C++11 才把这两个容器扶正。那一版实现的是非标准的 hash_map 和 hash_set,两个外壳都把工作交给同一份 hashtable:
// hash_set
typedef hashtable<Value, Value, HashFcn, identity<Value>, EqualKey, Alloc> ht;

// hash_map
typedef hashtable<pair<const Key, T>, Key, HashFcn,
                  select1st<pair<const Key, T>>, EqualKey, Alloc> ht;
底层模板的声明是:
template<class Value, class Key, class HashFcn,
         class ExtractKey, class EqualKey, class Alloc>
class hashtable;
Value 是结点里真正存放的对象,Key 是查找时认的关键字,HashFcn 把关键字算成整数,ExtractKey 从 Value 里取出关键字,EqualKey 判等,Alloc 管内存。算桶号、比相等时,哈希表只通过 ExtractKey 问“这个元素的关键字是什么”,元素里还有哪些字段,它不关心。
| 容器 | Value | Key | ExtractKey |
|---|---|---|---|
hash_set | Value(就是 K) | Value | identity<Value> |
hash_map | pair<const Key, T> | Key | select1st<pair<const Key, T>> |
同一份底层代码因此能服务两种容器。identity 原样返回,select1st 取 pair 的 first,两个“提货员”决定哈希表从哪里读关键字。
SGI 的 hash_set 把 iterator 和 const_iterator 都 typedef 成了 ht::const_iterator,它的迭代器天生只能读。原因不在底层,而在语义:set 的元素就是 key,改了元素等于改了哈希定位。标准库的 unordered_set::iterator 在类型上不是 const_iterator,但解引用同样返回 const Key&,约束没有放松。
把元素类型和关键字类型拆开
原来的哈希桶是 HashTable<K, V, Hash>,元素和关键字被绑死成同一对类型。要同时服务 set 和 map,得把元素类型独立出来,再加一个“提 key”参数:
template<class K, class T, class KeyOfT, class Hash = HashFunc<K>>
class HashTable;
K 只用于哈希和判等,T 是真正存进结点的东西。结点跟着改成只依赖 T:
template<class T>
struct HashNode
{
    T _data;
    HashNode<T>* _next;
    HashNode(const T& data) : _data(data), _next(nullptr) {}
};
set 传 T = const K,map 传 T = std::pair<const K, V>。为什么 set 的元素类型要带 const,后面单独说。
外层容器各提供一个 KeyOfT:
struct SetKeyOfT
{
    const K& operator()(const K& key) const { return key; }
};

struct MapKeyOfT
{
    const K& operator()(const std::pair<const K, V>& kv) const { return kv.first; }
};
set 的元素本来就是 K,这个原样返回的仿函数看起来多余。它不是给容器用的,是给底层用的:哈希表只会“从 T 里取出 K”这一个动作,如果 set 省掉这一步,底层就得为“T 等于 K”和“T 是 pair”写两套分支,泛型立刻裂开。
用仿函数而不是函数指针,是因为仿函数是类型的一部分。编译器可以为 set 和 map 各实例化一份 HashTable,把 kot(x) 内联进 Find 和 Insert,省掉一次间接调用。函数指针是运行期的值,做不到这件事。
Insert 返回 pair,operator[] 才有一次查找
Insert 先判重,再扩容,最后头插,返回 std::pair<Iterator, bool>。second 表示这次到底插没插进去,first 指向已存在或刚插入的元素。operator[] 就靠它一次查找完成“有则取、无则建”:
V& operator[](const K& key)
{
    std::pair<iterator, bool> ret = _ht.Insert(std::pair<const K, V>(key, V()));
    return ret.first->second;
}
只返回 bool 的话,取值时还得再 Find 一次。operator[] 永远保证键存在,所以判断键在不在不能用它;一次 dict["string"] 就会插入一条值初始化的记录。
迭代器要带一个表指针
哈希桶是“桶数组加桶内链表”的二维结构。list 的迭代器只存一个结点指针就能走完全程,因为结点自带 next;哈希表走到当前链的链尾时,_next 是空,而“下一个非空桶在哪”的信息不在结点里,只有桶数组知道。
解法是在迭代器里放两个指针:_node 指着当前结点,负责解引用和桶内前进;_pht 指着哈希表对象,负责链走完后跨到下一个非空桶。
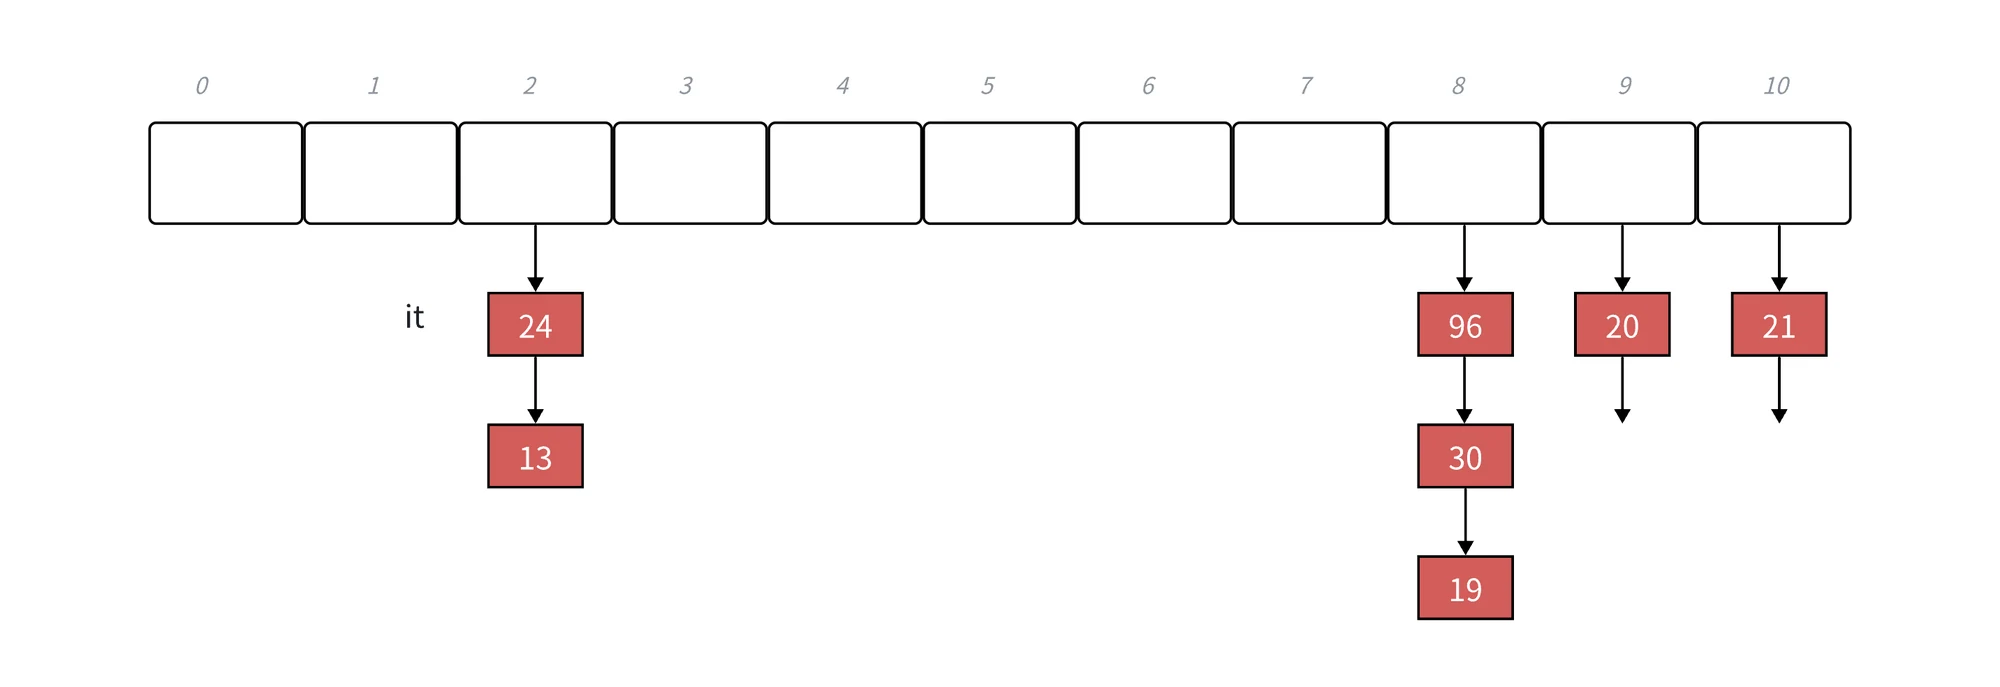
Self& operator++()
{
    if (_node->_next != nullptr)
    {
        _node = _node->_next;
        return *this;
    }

    KeyOfT kot;
    Hash hs;
    std::size_t hashi = hs(kot(_node->_data)) % _pht->_tables.size();
    ++hashi;
    while (hashi < _pht->_tables.size() && _pht->_tables[hashi] == nullptr)
        ++hashi;

    _node = (hashi == _pht->_tables.size()) ? nullptr : _pht->_tables[hashi];
    return *this;
}
为什么不把“当前桶号”也存进迭代器?那会引入冗余状态,拷贝、比较、赋值时都要维护。反推桶号的代价是每条链末尾多算一次哈希,均摊很小。
begin() 找第一个非空桶,end() 用空指针当哨兵:
Iterator Begin()
{
    for (std::size_t i = 0; i < _tables.size(); ++i)
        if (_tables[i] != nullptr)
            return Iterator(_tables[i], this);
    return End();
}

Iterator End()
{
    return Iterator(nullptr, this);
}
迭代器类别是单向迭代器。标准里 unordered_set::iterator 是 LegacyForwardIterator,只能 ++,不能 --,也不能用在 std::reverse 这类要求双向迭代器的算法上。范围 for 只需要 begin、end、!=、++,够用。
失效规则分三种:插入触发 rehash,桶数组换了,所有迭代器失效;删除某个元素,只有指向它的迭代器失效;插入没触发扩容,已有迭代器仍然有效,新结点可能插在某个链头,遍历顺序会变。边遍历边删除要先保存下一个位置,或者用 it = erase(it) 的写法。
迭代器能靠结点反推桶号,前提是哈希函数对同一个键永远给出同一个值。如果 Hash 带可变状态,比如每次调用换一个随机种子,插入时按种子 A 挂进桶,迭代器 ++ 时按种子 B 反推,就会从错误的桶继续走,遍历漏元素。标准要求哈希函数对相等的键返回相同结果,改造品也得守住这条。
标准容器还提供 iterator 到 const_iterator 的隐式转换。这里用 Ptr 和 Ref 两个模板参数分别实例化两种迭代器:begin() const 直接返回 ConstIterator,解引用得到 const T&。unordered_set 的两种迭代器解引用结果都是 const K&,因为它的 T 本身就是 const K。
const K 与 pair<const K, V>
set 的元素类型必须是 const K。元素本身就是 key,key 的哈希值决定它落在哪个桶;允许修改的话,改完哈希值对应另一个桶,元素还物理地留在旧桶,后续 find 按新值去新桶找,永远找不到。
cppreference 的 unordered_set 页面第一条就写了:容器元素不可修改,即使通过非 const 迭代器也不行,因为修改会改变哈希、破坏容器。T = const K 让这条约束在编译期生效,*it 返回 const K&,赋值直接报错。
map 的元素是 pair<const K, V>,first 是 const,second 可变。标准里 unordered_map::value_type 就写作 std::pair<const Key, T>。it->second += 'x' 合法,it->first = "xxx" 编译失败。关键字是身份,值只是内容,这个不对称是故意的。
自定义类型当键时,哈希与相等必须一致:== 比了哪几个字段,哈希就得把哪几个字段掺进去。== 只比年份、哈希却算年月日,两个“相等”的键会落进不同桶,find 永远遇不到;反过来不会查错,但同年份的键全挤进一个桶,O(1) 退化成一个链表。
标准容器还会在类内暴露 key_type、mapped_type、value_type、hasher、key_equal、allocator_type,它们都是模板参数的别名。写自己的容器时把这几个别名照抄,按标准名字取类型的泛型代码才能复用。value_type 在 set 里是 const K,在 map 里是 pair<const K, V>,这正是两个 T 的来源。
两份容器和一张表的完整代码
#include <algorithm>
#include <cstddef>
#include <iostream>
#include <string>
#include <utility>
#include <vector>

template<class K>
struct HashFunc
{
    std::size_t operator()(const K& key) const
    {
        return static_cast<std::size_t>(key);
    }
};

template<>
struct HashFunc<std::string>
{
    std::size_t operator()(const std::string& key) const
    {
        std::size_t h = 0;
        for (unsigned char ch : key)
            h = h * 131 + ch;
        return h;
    }
};

inline std::size_t next_prime(std::size_t n)
{
    static const std::size_t primes[] =
    {
        53, 97, 193, 389, 769,
        1543, 3079, 6151, 12289, 24593,
        49157, 98317, 196613, 393241, 786433,
        1572869, 3145739, 6291469, 12582917, 25165843,
        50331653, 100663319, 201326611, 402653189, 805306457,
        1610612741, 3221225473u, 4294967291u
    };
    const std::size_t count = sizeof(primes) / sizeof(primes[0]);
    const std::size_t* pos = std::lower_bound(primes, primes + count, n);
    return pos == primes + count ? primes[count - 1] : *pos;
}

template<class T>
struct HashNode
{
    T _data;
    HashNode<T>* _next;

    HashNode(const T& data)
        : _data(data), _next(nullptr) {}
};

template<class K, class T, class KeyOfT, class Hash>
class HashTable;

template<class K, class T, class Ptr, class Ref, class KeyOfT, class Hash>
struct HTIterator
{
    using Node = HashNode<T>;
    using Self = HTIterator<K, T, Ptr, Ref, KeyOfT, Hash>;

    Node* _node;
    const HashTable<K, T, KeyOfT, Hash>* _pht;

    HTIterator(Node* node, const HashTable<K, T, KeyOfT, Hash>* pht)
        : _node(node), _pht(pht) {}

    Ref operator*() const
    {
        return _node->_data;
    }

    Ptr operator->() const
    {
        return &_node->_data;
    }

    bool operator==(const Self& other) const
    {
        return _node == other._node;
    }

    bool operator!=(const Self& other) const
    {
        return _node != other._node;
    }

    Self& operator++()
    {
        if (_node->_next != nullptr)
        {
            _node = _node->_next;
            return *this;
        }

        KeyOfT kot;
        Hash hs;
        std::size_t hashi = hs(kot(_node->_data)) % _pht->_tables.size();
        ++hashi;
        while (hashi < _pht->_tables.size() && _pht->_tables[hashi] == nullptr)
            ++hashi;

        _node = (hashi == _pht->_tables.size()) ? nullptr : _pht->_tables[hashi];
        return *this;
    }
};

template<class K, class T, class KeyOfT, class Hash>
class HashTable
{
    template<class KK, class TT, class PP, class RR, class KOT, class HH>
    friend struct HTIterator;

    using Node = HashNode<T>;

public:
    using Iterator = HTIterator<K, T, T*, T&, KeyOfT, Hash>;
    using ConstIterator = HTIterator<K, T, const T*, const T&, KeyOfT, Hash>;

    HashTable()
    {
        _tables.resize(next_prime(0), nullptr);
    }

    ~HashTable()
    {
        Clear();
    }

    HashTable(const HashTable&) = delete;
    HashTable& operator=(const HashTable&) = delete;

    Iterator Begin()
    {
        for (std::size_t i = 0; i < _tables.size(); ++i)
            if (_tables[i] != nullptr)
                return Iterator(_tables[i], this);
        return End();
    }

    Iterator End()
    {
        return Iterator(nullptr, this);
    }

    ConstIterator Begin() const
    {
        for (std::size_t i = 0; i < _tables.size(); ++i)
            if (_tables[i] != nullptr)
                return ConstIterator(_tables[i], this);
        return End();
    }

    ConstIterator End() const
    {
        return ConstIterator(nullptr, this);
    }

    std::pair<Iterator, bool> Insert(const T& data)
    {
        KeyOfT kot;
        Iterator it = Find(kot(data));
        if (it != End())
            return std::make_pair(it, false);

        Hash hs;
        if (_n == _tables.size())
        {
            std::vector<Node*> newTables(next_prime(_tables.size() + 1), nullptr);
            for (std::size_t i = 0; i < _tables.size(); ++i)
            {
                Node* cur = _tables[i];
                while (cur != nullptr)
                {
                    Node* next = cur->_next;
                    std::size_t hashi = hs(kot(cur->_data)) % newTables.size();
                    cur->_next = newTables[hashi];
                    newTables[hashi] = cur;
                    cur = next;
                }
                _tables[i] = nullptr;
            }
            _tables.swap(newTables);
        }

        std::size_t hashi = hs(kot(data)) % _tables.size();
        Node* node = new Node(data);
        node->_next = _tables[hashi];
        _tables[hashi] = node;
        ++_n;
        return std::make_pair(Iterator(node, this), true);
    }

    Iterator Find(const K& key)
    {
        KeyOfT kot;
        Hash hs;
        std::size_t hashi = hs(key) % _tables.size();
        for (Node* cur = _tables[hashi]; cur != nullptr; cur = cur->_next)
        {
            if (kot(cur->_data) == key)
                return Iterator(cur, this);
        }
        return End();
    }

    ConstIterator Find(const K& key) const
    {
        KeyOfT kot;
        Hash hs;
        std::size_t hashi = hs(key) % _tables.size();
        for (Node* cur = _tables[hashi]; cur != nullptr; cur = cur->_next)
        {
            if (kot(cur->_data) == key)
                return ConstIterator(cur, this);
        }
        return End();
    }

    bool Erase(const K& key)
    {
        KeyOfT kot;
        Hash hs;
        std::size_t hashi = hs(key) % _tables.size();
        Node* prev = nullptr;
        Node* cur = _tables[hashi];
        while (cur != nullptr)
        {
            if (kot(cur->_data) == key)
            {
                if (prev == nullptr)
                    _tables[hashi] = cur->_next;
                else
                    prev->_next = cur->_next;
                delete cur;
                --_n;
                return true;
            }
            prev = cur;
            cur = cur->_next;
        }
        return false;
    }

private:
    void Clear() noexcept
    {
        for (std::size_t i = 0; i < _tables.size(); ++i)
        {
            Node* cur = _tables[i];
            while (cur != nullptr)
            {
                Node* next = cur->_next;
                delete cur;
                cur = next;
            }
            _tables[i] = nullptr;
        }
        _n = 0;
    }

    std::vector<Node*> _tables;
    std::size_t _n = 0;
};

namespace bit
{
template<class K, class Hash = HashFunc<K>>
class unordered_set
{
    struct SetKeyOfT
    {
        const K& operator()(const K& key) const { return key; }
    };

public:
    using iterator = typename HashTable<K, const K, SetKeyOfT, Hash>::Iterator;
    using const_iterator = typename HashTable<K, const K, SetKeyOfT, Hash>::ConstIterator;

    iterator begin() { return _ht.Begin(); }
    iterator end() { return _ht.End(); }
    const_iterator begin() const { return _ht.Begin(); }
    const_iterator end() const { return _ht.End(); }

    std::pair<iterator, bool> insert(const K& key)
    {
        return _ht.Insert(key);
    }

    iterator find(const K& key) { return _ht.Find(key); }
    const_iterator find(const K& key) const { return _ht.Find(key); }

    bool erase(const K& key)
    {
        return _ht.Erase(key);
    }

private:
    HashTable<K, const K, SetKeyOfT, Hash> _ht;
};

template<class K, class V, class Hash = HashFunc<K>>
class unordered_map
{
    struct MapKeyOfT
    {
        const K& operator()(const std::pair<const K, V>& kv) const { return kv.first; }
    };

public:
    using iterator = typename HashTable<K, std::pair<const K, V>, MapKeyOfT, Hash>::Iterator;
    using const_iterator = typename HashTable<K, std::pair<const K, V>, MapKeyOfT, Hash>::ConstIterator;

    iterator begin() { return _ht.Begin(); }
    iterator end() { return _ht.End(); }
    const_iterator begin() const { return _ht.Begin(); }
    const_iterator end() const { return _ht.End(); }

    std::pair<iterator, bool> insert(const std::pair<const K, V>& kv)
    {
        return _ht.Insert(kv);
    }

    V& operator[](const K& key)
    {
        std::pair<iterator, bool> ret = _ht.Insert(std::pair<const K, V>(key, V()));
        return ret.first->second;
    }

    iterator find(const K& key) { return _ht.Find(key); }
    const_iterator find(const K& key) const { return _ht.Find(key); }

    bool erase(const K& key)
    {
        return _ht.Erase(key);
    }

private:
    HashTable<K, std::pair<const K, V>, MapKeyOfT, Hash> _ht;
};
}

int main()
{
    bit::unordered_set<int> s;
    int a[] = {4, 2, 6, 1, 3, 5, 15, 7, 16, 14, 3, 3, 15};
    for (int e : a)
        s.insert(e);

    for (auto e : s)
        std::cout << e << ' ';
    std::cout << '\n';

    bit::unordered_map<std::string, std::string> dict;
    dict.insert({"sort", "排序"});
    dict.insert({"left", "左边"});
    dict["insert"] = "插入";
    dict["string"];

    for (auto& kv : dict)
        std::cout << kv.first << ':' << kv.second << '\n';

    return 0;
}
哈希表的桶里存的是裸结点指针。默认拷贝构造会复制桶数组,两个表指向同一批结点,析构时同一块内存被 delete 两次;所以实现里把拷贝构造和拷贝赋值删除了。要真的拷贝,得逐桶遍历、为每个结点 new 一份,再按新表长重新挂链。用 vector<Node> 整体复制会让结点地址变化,桶里的 _next 和外部保存的地址都会失效。课件也提醒拷贝构造和拷贝赋值需要自己实现深拷贝。
扩容条件是 _n == _tables.size(),即负载因子到 1:桶数用 next_prime(size + 1) 找下一个质数,旧结点逐个摘下、按新表长重新算桶号、头插进新桶。全程没有 new Node,结点地址不变,指向元素的引用和指针仍然有效。
erase 在标准容器里返回删除个数;set 和 map 的键唯一,返回值只能是 0 或 1。这里的接口用 bool 承接,语义等价。count 在 unordered_set 上也是 0 或 1,只有 multi 版本才可能大于 1。
课件代码里的三处顺序问题
第一处在过渡版:if (Find(kot(data)) return false;。这里的 Find 最终返回迭代器,迭代器没有到 bool 的转换,这行按最终接口编不过,必须写成 if (Find(kot(data)) != End())。
第二处在过渡版扩容:newtables(__stl_next_prime(_tables.size()))。_tables.size() 本身就是质数,next_prime 返回的还是它,新表一点没变大;下一次插入又满足 _n == _tables.size(),整张表被反复重建。参数要传 _tables.size() + 1。
第三处出现在最终版:桶号在扩容之前算好,扩容后直接拿旧下标头插。桶数从 53 变成 97 后,同一个 key 的桶号可能从 47 变成 3,结点挂到 47 号桶,Find 按新表长去 3 号桶找,找不到。顺序是“先扩容,再用新表长算桶号”。
另外,课件里 MapKeyOfT 的形参写成 const pair<K, V>&,而 T 实际是 pair<const K, V>。它能编过,是因为 std::pair 有转换构造函数,会造一个临时对象再绑定;直接写 pair<const K, V> 少一次拷贝,也和 value_type 一致。
这套封装把变化点集中到了三个位置:元素类型 T、提取 key 的 KeyOfT、迭代器里的表指针。哈希表的 Insert、Find、Erase 只认 K,桶里躺的是 K 还是 pair<const K, V>,它们不关心。set 和 map 的外壳因此只剩类型别名和几个转发函数。
还没有评论 — 第一条由你来留。